> For the complete documentation index, see [llms.txt](https://docs.avonnicomponents.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.avonnicomponents.com/flow/tutorials/components/csv-parser/101-tutorial.md).

# Import a CSV file in a screen flow

Build a screen flow that turns a CSV of trade show booth scans into Leads, with the file checked and mapped on screen before one Create Records saves it.

Your events team comes back from a trade show with a spreadsheet of booth scans and wants them in Salesforce as Leads today. With the [CSV Parser](/flow/flow-components/csv-parser.md) on a flow screen, the user drops the file, checks which column goes to which Lead field, and presses Next. One Create Records element saves the rows.

<figure><img src="https://27923732-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F1FUd4apB9YHgCEMUFbVb%2Fuploads%2F4aJwqlQ6QRd4HA4qiAVr%2Fcsv-101-tutorial-result.png?alt=media" alt="A flow screen after a CSV upload: the upload control, the text Found 5 rows, a Mapping section where seven CSV headers with sample values point to First Name, Last Name, Company, Title, Email, Phone and Description, and an Import leads button."><figcaption><p>Five booth leads read from the file, every column matched to a Lead field.</p></figcaption></figure>

## Before you start

* Avonni Flow Components is installed in your org, and you can create flows and Leads.
* You have a CSV file to test with. Copy the sample below into a text editor and save it as `booth-leads.csv`, in UTF-8.
* Run your first tests in a sandbox, or plan to delete the test Leads afterwards: the last step creates real records.

```csv
First Name,Last Name,Company,Job title,Email,Phone,Booth notes
Maya,Okafor,Harbour Point Logistics,Head of Operations,maya.okafor@harbourpoint.example,(617) 555-0142,Wants a demo for the Boston warehouse team
Daniel,Reyes,Kestrel Cold Chain,IT Director,d.reyes@kestrelcold.example,(312) 555-0187,Asked about temperature alerts on shipments
Priya,Natarajan,Lumen Frieght,VP Supply Chain,priya.n@lumenfreight.example,(415) 555-0119,Evaluating carriers for Q1
Tom,Becker,Northgate Distribution,Fleet Manager,tbecker@northgate.example,(206) 555-0164,Runs 40 trucks. Follow up next week
Sofia,Marchetti,Alta Via Imports,Operations Manager,sofia.marchetti@altavia.example,(646) 555-0133,Scanned badge only
```

## Steps

{% stepper %}
{% step %}

### Create a screen flow and its first screen

1. In Setup, open Flows and create a new Screen Flow.
2. Add a Screen element right after Start. Label it `Upload Leads`.
   {% endstep %}

{% step %}

### Add the CSV Parser to the screen

1. In the screen's component list, search for `CSV Parser` and drag **Avonni CSV Parser** onto the screen.
2. Give it an API Name you will recognize later, for example `leadCsv`. You will pick its output by this name in a later step.

The screen canvas shows "No preview is available for this component." That is expected. Click the component: its main settings load in the panel on the right, which can take several seconds the first time. Everything this tutorial needs is in that panel. The **Open Component Builder** button at its top opens the full settings, including the **Parser** and **Save As Content Document** groups, next to a live preview.
{% endstep %}

{% step %}

### Point the parser at the Lead object

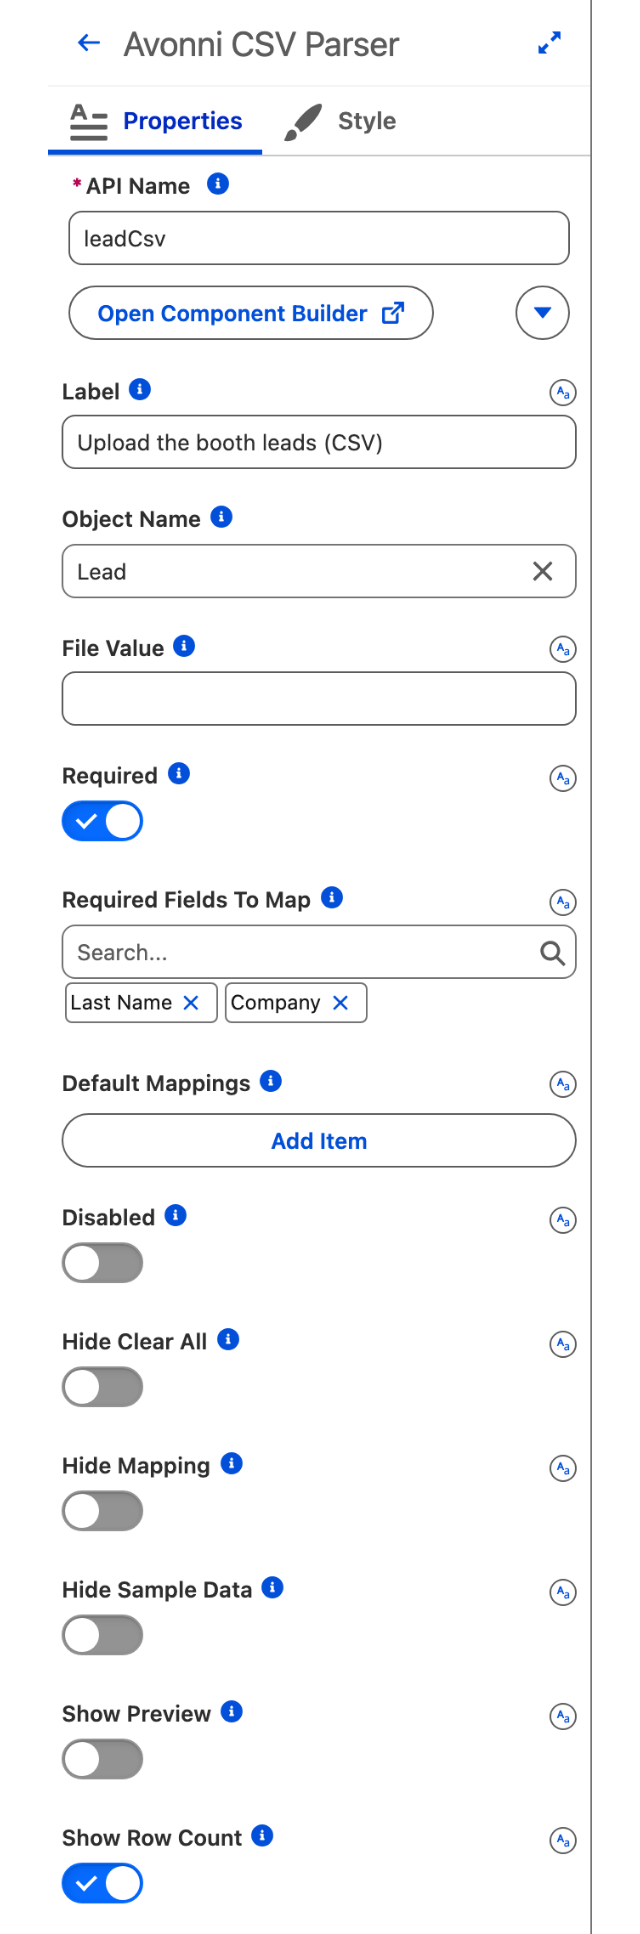
1. **Object Name**: select `Lead`. The default is `Account`.
2. **Label**: replace the default `Upload Accounts CSV` with something your users understand, such as `Upload the booth leads (CSV)`.

**Object Name** does two jobs. It sets the fields offered in the mapping, and it makes the **Records** output a collection of Leads, which is what Create Records expects later.
{% endstep %}

{% step %}

### Decide what the file must contain

1. Turn on **Required**. Without a file, Next stops with "Required CSV file missing."
2. In **Required Fields To Map**, select `Last Name` and `Company`. A Lead cannot be saved without them, so the screen checks for them before anything else runs.
3. Turn on **Show Row Count**. After the upload, the user reads "Found 5 rows." under the drop zone and knows the file was read.
4. Leave **Hide Mapping** off. It is off by default, and it keeps the mapping section visible so the user can check and fix each column.

<figure><img src="https://27923732-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F1FUd4apB9YHgCEMUFbVb%2Fuploads%2F72K4yPLaQUerZJODy0Lk%2Fcsv-101-tutorial-panel.png?alt=media" alt="The CSV Parser settings in the Flow Builder screen editor: Open Component Builder button, Label, Object Name set to Lead, Required on, Required Fields To Map with Last Name and Company, Show Row Count on." width="320"><figcaption><p>The CSV Parser settings in the screen editor's right panel.</p></figcaption></figure>
{% endstep %}

{% step %}

### Keep the standard Next button

The flow's own footer moves the user to the next element. You do not need an extra button on the screen. If you want a clearer word than Next, rename it in the screen's footer settings, for example `Import leads`.

When the user presses Next, the CSV Parser runs its checks: a missing file or an unmapped required field keeps the user on the screen with a message.
{% endstep %}

{% step %}

### Save the rows with Create Records

1. After the screen, add a Create Records element. Label it `Create Leads`.
2. Choose to create multiple records from a collection.
3. Open the collection picker and type the API name of your parser, `leadCsv`. Select it, then select **Records**. The reference reads `{!leadCsv.records}`.

**Records** holds one Lead per row of the file, with each value in the field its column was mapped to. The parser also exposes **Records Serialized** (the same rows as JSON text) and **Content Document Id** (used when the file is saved in Salesforce). For this flow you only need **Records**.
{% endstep %}

{% step %}

### Save and test

1. Save the flow, then click Debug or Run.
2. Upload `booth-leads.csv`. The mapping section lists the seven headers, each with its first three values under it.
3. `Company`, `Email` and `Phone` are already matched, because their headers are spelled exactly like the field API names. The other four show an empty picker.
4. Pick a field for each empty one: First Name, Last Name, Title (for Job title) and Description (for Booth notes).
5. Check that "Found 5 rows." is shown, then press Next.

<figure><img src="https://27923732-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F1FUd4apB9YHgCEMUFbVb%2Fuploads%2Fbor0emKU48xgwRKFgA6P%2Fcsv-101-tutorial-mapping.png?alt=media" alt="A flow screen after a CSV upload: Found 5 rows, and a Mapping section where Company, Email and Phone are matched and First Name, Last Name, Job title and Booth notes have an empty field picker."><figcaption><p>Headers spelled like a field API name match on their own, the others wait for a pick.</p></figcaption></figure>

Open the Leads tab: the five booth leads are there, with the booth notes in Description. If the same export comes back every month, set those four matches once in the flow so the user never has to pick them: see [Pre-map CSV columns for a recurring import](/flow/tutorials/components/csv-parser/pre-map-csv-columns.md).
{% endstep %}
{% endstepper %}

## Troubleshooting

<details>

<summary>Next shows "Required Headers Not Found: LastName. Please add them and try again."</summary>

A field listed in **Required Fields To Map** has no column mapped to it. Usually the file names the column differently (for example `Surname`) and the user did not pick a field for it. After this message the mapping section is no longer shown, so the user fixes the file and uploads it again. To prevent it, add a **Default Mappings** entry for each spelling your files use. [Pre-map CSV columns for a recurring import](/flow/tutorials/components/csv-parser/pre-map-csv-columns.md) shows how.

</details>

<details>

<summary>A column shows an empty picker although the field exists</summary>

The header is not spelled exactly like the field's API name (`email` is not `Email`). The user can pick the field in the picker, or you can map that header once in **Default Mappings**. [Pre-map CSV columns for a recurring import](/flow/tutorials/components/csv-parser/pre-map-csv-columns.md) lists the matching rules.

</details>

<details>

<summary>The field I want is not offered in a column's picker</summary>

The picker only offers fields whose type fits the column's first value. A column of email addresses is not offered number, date or checkbox fields, for example. A field already used by another column is shown but cannot be selected: clear it from the other column first.

</details>

<details>

<summary>Accented characters look wrong after the upload</summary>

The file was not saved in UTF-8, which is what the parser reads by default. [Fix encoding and delimiter issues](/flow/tutorials/components/csv-parser/fix-encoding-and-delimiter-issues.md) shows how to tell which encoding the file uses and where to set it.

</details>

<details>

<summary>"The uploaded CSV file exceeded the rows limit. Only the first 10000 rows were processed."</summary>

The file has more rows than the parser reads in one go. See [Fix encoding and delimiter issues](/flow/tutorials/components/csv-parser/fix-encoding-and-delimiter-issues.md) for the limit and what to do.

</details>

<details>

<summary>"Could not retrieve "Lead" object fields. Please verify the object name."</summary>

The parser could not load the fields of the object set in **Object Name**. Check that the object is the right one and that the user running the flow can access it.

</details>

## Related tutorials

* [Pre-map CSV columns for a recurring import](/flow/tutorials/components/csv-parser/pre-map-csv-columns.md): set the column matches once so users only drop the file.
* [Review rows before saving](/flow/tutorials/components/csv-parser/review-rows-before-saving.md): show every row in a table on a second screen and fix mistakes, like `Lumen Frieght` in the sample, before they become Leads.
* [Import a file stored in Salesforce](/flow/tutorials/components/csv-parser/import-a-file-stored-in-salesforce.md): read a CSV already attached to a record instead of asking for an upload.
* [CSV Parser](/flow/flow-components/csv-parser.md): every setting of the component, in one place.


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.avonnicomponents.com/flow/tutorials/components/csv-parser/101-tutorial.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.